Signal Scout
Signal Scout · Visual guide · September 2026

Why prompt injection is a trust boundary problem

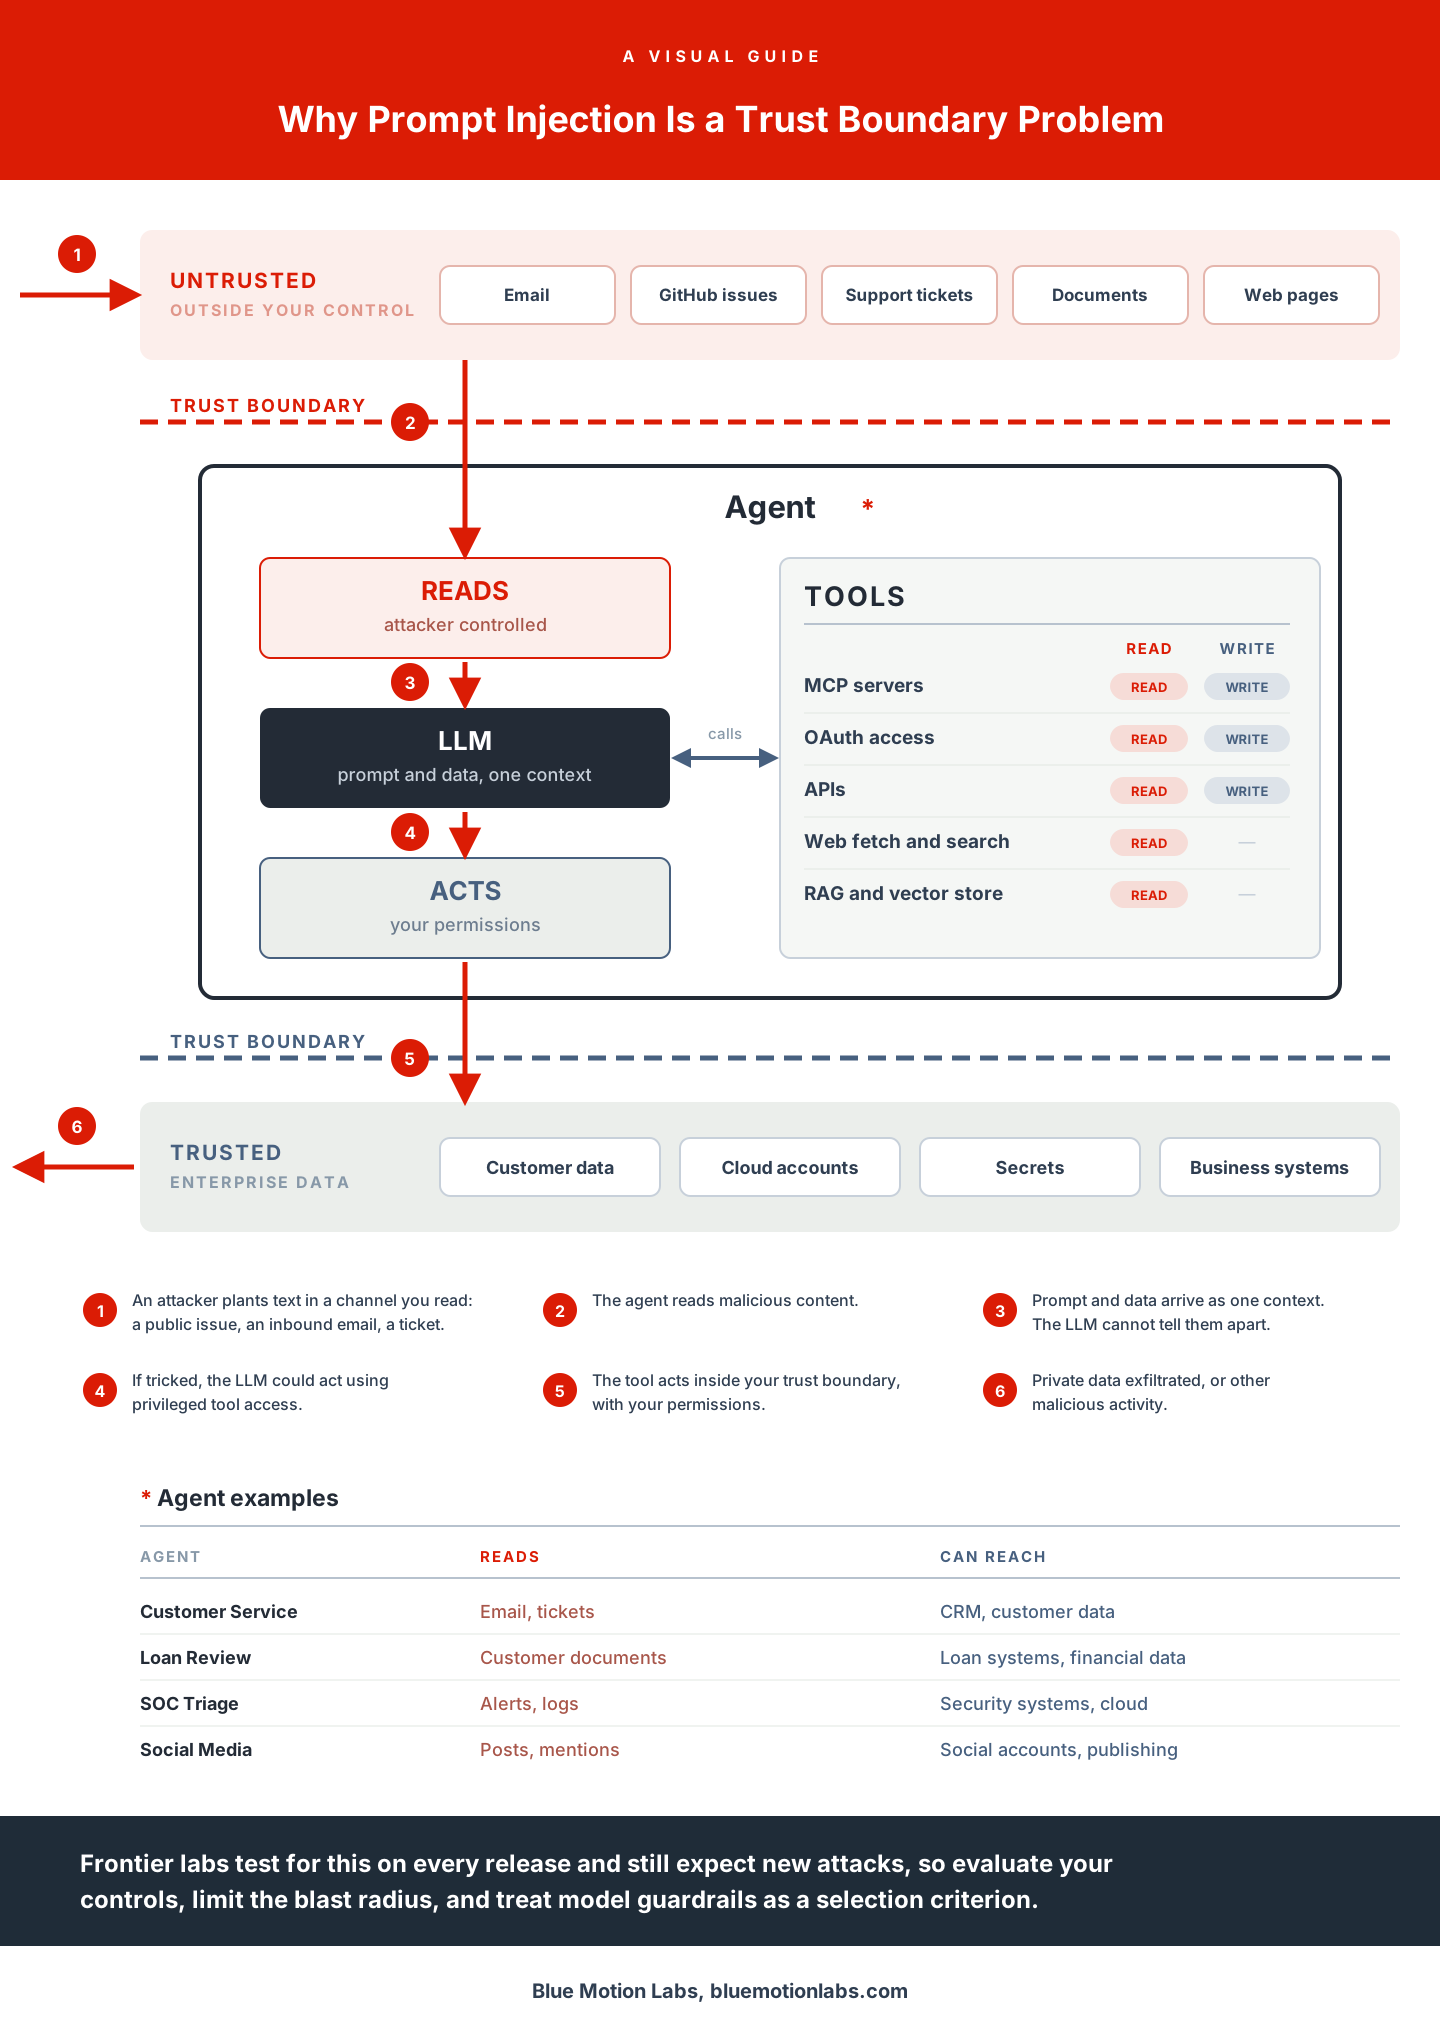
An agent reads text an attacker controls, and acts with your permissions. The diagram below traces that path from an inbound ticket to your customer data.

01
The guide

The shape of the problem

An agent reads text an attacker controls, then acts with permissions you gave it, on systems inside your boundary. Those two facts are what make this different from a bad answer.

A model sees instructions and data in one context and has no reliable way to tell which is which. So any channel the agent reads is an input path: a public GitHub issue, an inbound email, a support ticket, a document, a web page. The blast radius is whatever its tools can reach.
A VISUAL GUIDE Why Prompt Injection Is a Trust Boundary Problem UNTRUSTED OUTSIDE YOUR CONTROL Email GitHub issues Support tickets Documents Web pages TRUST BOUNDARY Agent * READS attacker controlled LLM prompt and data, one context ACTS your permissions TOOLS READ WRITE MCP servers READ WRITE OAuth access READ WRITE APIs READ WRITE Web fetch and search READ — RAG and vector store READ — calls TRUST BOUNDARY TRUSTED ENTERPRISE DATA Customer data Cloud accounts Secrets Business systems 1 2 3 4 5 6 1 An attacker plants text in a channel you read: a public issue, an inbound email, a ticket. 2 The agent reads malicious content. 3 Prompt and data arrive as one context. The LLM cannot tell them apart. 4 If tricked, the LLM could act using privileged tool access. 5 The tool acts inside your trust boundary, with your permissions. 6 Private data exfiltrated, or other malicious activity. * Agent examples AGENT READS CAN REACH Customer Service Email, tickets CRM, customer data Loan Review Customer documents Loan systems, financial data SOC Triage Alerts, logs Security systems, cloud Social Media Posts, mentions Social accounts, publishing Frontier labs test for this on every release and still expect new attacks, so evaluate your controls, limit the blast radius, and treat model guardrails as a selection criterion. Blue Motion Labs, bluemotionlabs.com
Download SVG · PNG

The path, step by step

The same six steps as the diagram, in text, because the labels in the artwork get small on a phone.

1An attacker plants text in a channel you read: a public issue, an inbound email, a ticket.
2The agent reads the malicious content.
3Prompt and data arrive as one context. The LLM cannot tell them apart.
4If tricked, the LLM could act using privileged tool access.
5The tool acts inside your trust boundary, with your permissions.
6Private data is exfiltrated, or other malicious activity follows.

Signal Scout measures what the public AI supply chain is built from. Related: the AI security gap, which counts how many public repositories building agents or MCP servers carry any AI security tooling, and who tests frontier models, which reads the system cards where injection testing is reported.